Login-less comments on this static site
Commenting here costs no account, no email and no confirmation link: you get a random animal avatar, and the comment becomes a public JSON file served straight from S3.
I like building playlists, and the best part is turning up something in my own library I had forgotten I owned. That got me curious about how music recommenders pick the next song, and whether the elaborate ones earn their complexity. So before building anything clever, I tested which signals actually work: with the method names hidden, I scored 1,100 proposed tracks on whether they belonged. One of the most obvious strategies did worse than random. I then scored another 1,100 on the same lists while the recommender learned from each score. That did not clearly beat a ranking that ignored those scores.
Key takeaways
- Global popularity is a bad playlist expander on this library. Conditioning it on tags helps; content and graph similarity help more.
- The useful complexity jump is onto an item similarity graph, not past it. SVD on that same graph failed; wrapping the good channels in a hybrid barely moved the mean.
- A global “add if score is at least 6” rule is the wrong product metric. Thresholds have to be playlist-specific.
- Letting the hybrid learn from my scores during a session added +0.20 points on average, and the interval includes zero. The gain that does show up is right after a track I rejected.
I will go over the motivation, the hypotheses, the methods, how the 30-second samples were chosen, the 25k similarity matrix, the results, the live session, the limits, and what I would actually conclude.
Putting a playlist together is a hobby of its own, and the best part is turning up a track I bought years ago and then never played. That gets harder as a library grows. With tens of thousands of files, every new playlist ends up built from the few hundred songs I happen to remember.
What is missing is playlist expansion: given a seed list, propose other songs from the library that fit it. Streaming services do this constantly, on their own catalogue. My own music library, which I listen to through Plex, mostly plays back the files and playlists that are already in it.
Before building that, I wanted to check my assumptions. The first half is one listener, one 25k pilot subset, eleven curated seed playlists, and frozen ranked lists. The second half uses the same lists and the same listener, but the ranking updates while I score.
I expected three kinds of signal to matter, in different amounts depending on the list. These were prior beliefs, not findings:
The ensemble hypothesis was that a hybrid which reweights those channels per playlist would beat any single family. The experiment can support or embarrass that story. It cannot turn a hypothesis into a result by restating it at the end.
The design is eleven seed playlists, ten frozen recommenders, and one blinded 100-track trial per playlist. Each method ranked tracks that were not already on the seed playlist, from a 25,000-track catalogue. I built each trial by round-robin assignment, so each method owned about 9 to 11 exclusive slots. A track could still appear on several methods’ lists; overlapping credit inflates graph, hybrid, and tag, so the ranking below uses exclusive ownership only.
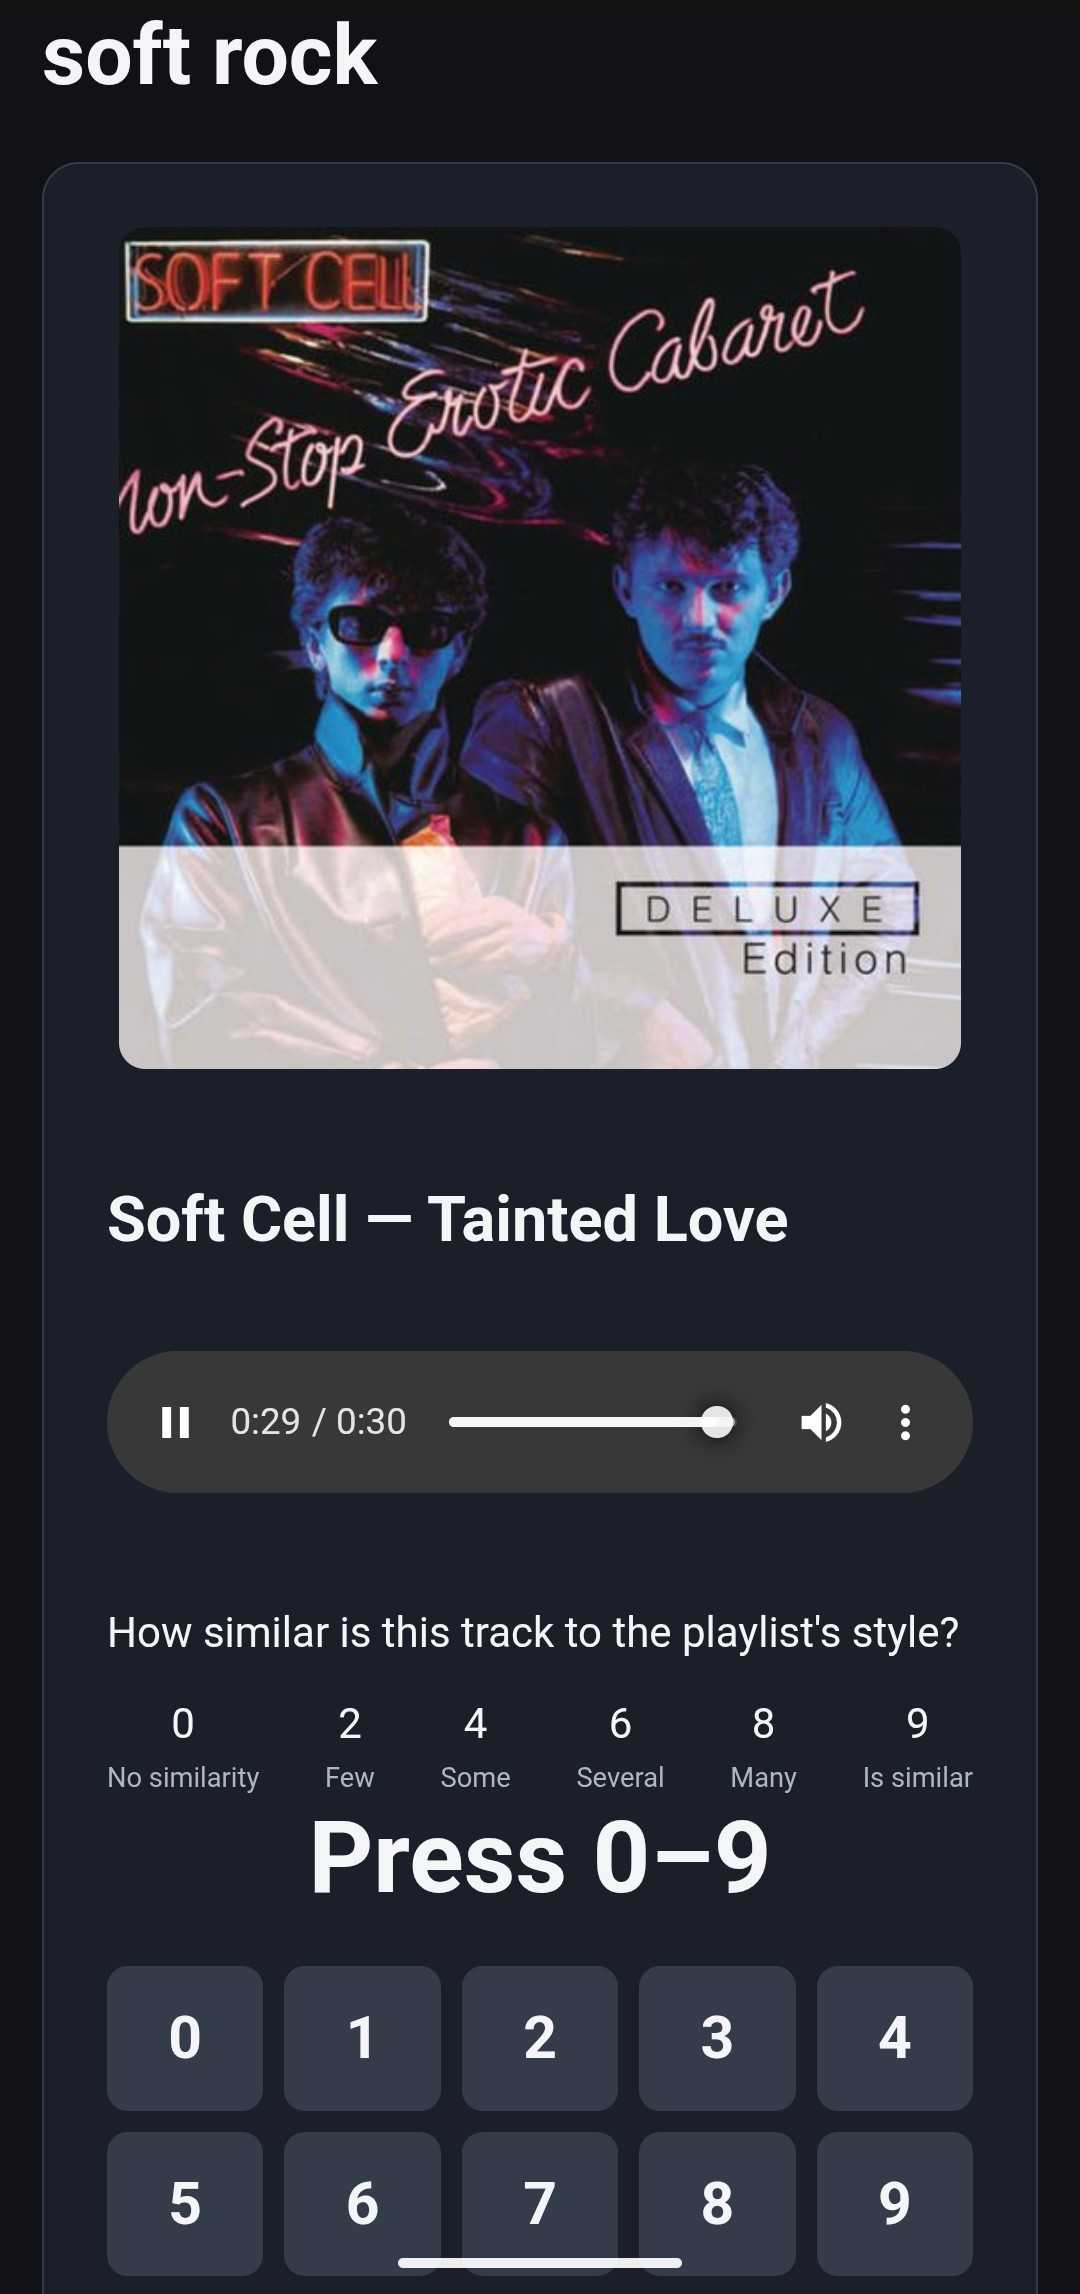
I scored every proposal from 0 to 9 on a numeric keypad: 0 means it does not belong, 9 means it belongs easily. The graded scale keeps more information than a yes/no click, and it is fast to operate one-handed while a preview plays. Method identity was hidden. All eleven trials were submitted (1,100 / 1,100).
The screen below is everything I had to go on: which playlist I was rating against, the track, its cover, and the keypad. Nothing on it says which recommender proposed the song.
The seed lists covered eleven different kinds of listening. During scoring I used only the intended fit as my criterion:
| Playlist type | What “fit” meant |
|---|---|
| Current hits | Mainstream songs that feel current |
| Crowd-pleasers | Familiar songs that work for a broad audience |
| Dutch party classics | Dutch-language party music |
| 80s-90s nostalgia | Synth-led nostalgia |
| Dance floor | High-energy dance tracks |
| Bossa nova / jazz | Relaxed bossa nova and jazz |
| Soul / easy listening | Slower soul and easy-listening tracks |
| Power ballads | Large, dramatic ballads |
| Indie discovery | Less obvious indie tracks worth discovering |
| Hard rock | Hard-rock tracks that fit together |
| Classic soft rock | Road-trip-friendly classic soft rock |
Ten frozen recommenders, simple to complex. Several names in the original plan were substituted, not faked: no Spotify popularity API, no LightGCN, no SASRec, no user-track ALS.
| Method | What it actually used |
|---|---|
| random | Uniform sample of eligible catalogue tracks |
| popularity | Last.fm playcount plus Plex views |
| tag_popularity | Popularity times overlap with seed tags, genre, or decade |
| tag | Cosine to a seed tag-vector centroid (tag SVD, no artist-name leakage) |
| sonic | k-nearest neighbours on acoustic descriptors plus Discogs-EffNet embeddings (a music-specific neural embedding) |
| item_item | Last.fm similar-track scores mapped onto the local catalogue |
| implicit_mf | SVD item factors of that similarity graph, not a user-track model |
| graph | Personalized PageRank on similar-track plus shared-tag edges |
| hybrid | Learned non-negative fusion of the channels above |
| multistage | Union of strong-channel candidates, then a diversity rerank (maximal marginal relevance) for artist spread and flow |
Controls (typically two held-out seed members and two hard negatives) sat in the trial so I would see some known goods and known bads. They are in the pooled histograms. They are not in the method ladder.
Every track was judged from one deterministic 30-second window, chosen to be the most representative part of the song. That rules out the two easy options: the opening 30 seconds of the file, and picking the window by compressed file size (that trick prefers silence or noise). I rated from that clip, the track name, and the album art.
Candidate 30-second windows were scored every 2 seconds from conventional acoustic features:
Representativeness is how close the window summary is to the track-wide feature centroid. Recurrence is similarity to non-adjacent sections elsewhere in the track (choruses and riffs beat one-off bridges). Activity asks for enough loudness and rhythmic or spectral content. Stability penalizes long silence and abrupt internal jumps. Intros, outros, and fades get a mild extra penalty. The design also prefers starts near beats or low-onset boundaries, and after the coarse pick it can nudge the start by about 3 seconds for a cleaner cut. I then rendered AAC at 96 kbit/s with very short fades so the clip does not click.
That one window is what I heard. The sonic recommender is a different use of 30-second audio: Discogs-EffNet sees three excerpts (the thumbnail, a non-overlapping middle, and another distinct region), pooled into an embedding. Rating from a chorus-like slice is not the same as embedding three slices.
The hard part of training on 25,000 tracks was memory, not modelling. Several methods share a dense item-item graph, and a 25,000 by 25,000 float32 adjacency matrix is about 2.5 GB before anyone copies it. PageRank and SVD make extra working copies, so that stage peaked around 8-9 GB, which the eight gigabytes in the machine could not hold. I added 16 GB to bring it to 24 GB, sized for train-recommenders. The extra memory was useful for the rest of the server anyway.
The same matrix is not one named recommender. It feeds:
The SVD rung used that graph as if it were a collaborative matrix. It is not a user-track model. That distinction matters when the rung collapses.
Some playlists are far more selective than others, and that difference matters more than any pooled average. Across all 1,100 scores the mean is 3.46 and 31% are zeros, but the current-hits playlist averages 4.14 with 45% of its scores at 6 or higher, while the 80s-90s nostalgia playlist averages 2.50 with 18% at 6 or higher. A product rule that adds a track only at 6 would accept almost half the current-hits trial and almost none of the bossa or nostalgia trials.
The pooled histogram below is the 0-9 scale as I actually used it: a large spike at zero, then a broad middle, not a clean accept/reject split.
Playlist means make the same point without pooling first. Current hits and soul / easy listening sit at the high end; classic soft rock and 80s-90s nostalgia sit at the low end.
On exclusive credit, popularity is worse than random (0.20 vs 0.55). The fitted hybrid put zero weight on raw popularity. Tag-conditioned popularity recovers to 2.88. Tag cosine, sonic kNN, and item-item then sit in the 4.5-4.9 range.
The largest drop on the ladder is item-item to implicit_mf (-3.34 mean points). The largest gain is implicit_mf to graph (+3.55). Hybrid edges the graph by 0.03 points; multistage sits with them. Playlist-clustered bootstrap intervals (resample the eleven playlist means) overlap for hybrid, graph, and multistage. Those intervals ask how the average moves if we reweight these playlist types. They are not a p-value for another listener, and they do not pick a winner.
Held to a threshold that lets through at most 1 in 5 random tracks, the methods surface 656 tracks at about 2% random contamination. That number needs its bar explained, because a classical ROC curve is not available here: it would need a binary label for every candidate and a true-positive rate against the whole catalogue, and I have neither. Scores are “does this belong on this playlist?”, and the negative class I can actually calibrate is the ~10 random items in each trial. So for each playlist I took the lowest integer threshold at which at most 1 in 5 of those randoms pass, then counted how many non-random, non-control tracks also pass. Because random is almost all zeros, that threshold is 1 on most lists (not a zero), with current hits the strict exception at 7. It is a weak bar, and it is the honest operating-point analogue of an ROC here.
Learned hybrid weights, for the record: sonic 0.27, tag 0.25, item-item 0.20, graph 0.15, implicit_mf 0.07, tag_popularity 0.06, popularity 0.
Which family wins changes from one playlist to the next, and raw popularity never wins on any of them. Grouping the methods into families (baseline, popularity, metadata, sonic, collaborative, fusion) and taking mean exclusive scores per playlist, sonic leads on hard rock, power ballads, dance-floor, 80s nostalgia, and classic soft rock. Fusion or collaborative lead on Dutch-language party, current hits, soul/easy listening, bossa/jazz, crowd-pleasers, and indie.
That is the part of the original hypothesis that survived: language-and-culture lists are not the same problem as a production niche. Dutch party classics are the clean example. Sonic mean 2.30; collaborative 5.96; fusion 6.17. Hard rock flips it: sonic 6.10, fusion 5.11. Power ballads are even more sonic-led (6.80 vs fusion 4.28).
Cells in the grid below are noisy (about 10 exclusive items per method per playlist), so family averages are the stable read, not any single square.
Treated as qualities rather than named products, tags and sound are the channels that help, and global popularity actively hurts. A regression of the human score on z-scored channel features plus playlist intercepts (n = 1,058, R squared = 0.50) puts tag-conditioned popularity, tag cosine, and sonic similarity on the positive side, and global popularity at -1.26 points per standard deviation once playlist identity is in the model. There are no coefficient standard errors in the export, so I treat this as a ranking of channels, not a significance table.
The frozen lists do not say whether the recommender should keep updating while I listen. I scored the same eleven playlists again, another 1,100 tracks, method still hidden. Averaged over the three copies that learned, updating did not clearly beat ignoring the scores. The gap is +0.20 points (95% interval -0.07 to +0.48). A test that flips the sign of each playlist’s gap gives p = 0.14, and the learning copies were ahead on 6 of the 11 lists. With eleven playlists, a gap under about 0.3 points will not show up, and this one does not.
Each session played 100 tracks and rotated through four copies of a hybrid, 25 tracks each. A track already on the seed list, or already played in the session, was not proposed again. Only the copy that proposed a track learned from my score of it.
One copy is frozen. It is trained once and then ignores every score. It is not the hybrid rung in the ladder above: that rung used k-nearest-neighbour sonic scoring, decade tags, and a training split.
The other three start from the same profile and then update, each from its own tracks only. Positive adds a track to its profile when I score it 6 or higher. Signed does that too, and also moves the profile away from tracks I score below 4.5, the midpoint of the scale. Bandit shifts weight toward the channels whose scores agreed with mine.
The four copies draw on the same top of the ranking, so the frozen copy has to reach deeper as the session goes on. Its median pick was rank 35, and its ratings fall from 6.55 inside its top 25 to 5.49 at ranks 51-100. A gap against the learning copies is partly the frozen copy having to dig that far.
The means were 6.05 for the frozen copy, 6.19 for positive, 6.19 for signed, and 6.37 for the bandit. Positive and signed landing on the same mean is the totals matching, not the same tracks. The bandit is the largest single gap, at +0.32 (p = 0.19). The intervals over the eleven playlist means overlap.
These means sit near 6, while the hybrid rung above sits near 5, because these sessions only played tracks a hybrid had already ranked near the top. The same tracks also scored 1.43 points higher in the live sessions than in the August and September trials (487 pairs, interval 0.77 to 2.21). After subtracting that shift, the live copies sit about level with the best frozen methods, and the shift is larger than the gaps between those methods. On that shifted comparison the bandit lands 0.17 below the old hybrid rung and 0.09 below multistage. I treat that as a coarse ranking across two designs, not a winner.
Which copy leads still depends on the playlist. The bandit is ahead on Dutch party classics and on power ballads. Positive is ahead on indie discovery. The frozen copy is narrowly ahead on hard rock. Soul / easy listening already has a high frozen score, and the learning copies do not improve it on average. Rows in the grid below run from the largest average gain over the frozen copy down to the largest loss.
After I scored a copy’s own previous pick at 3 or lower, its next pick beat the frozen copy’s pick at the same point in the session by about 0.6 to 1.2 points, with the bandit at the high end. After a pick I had scored 6 or higher, the gap was about 0 to 0.3. The frozen copy keeps serving the same region of its list. The learning copies can leave that region.
Seed lists of 30 tracks or fewer gained +0.46, across 6 lists. The 5 longer lists lost 0.11. That split is descriptive. Indie discovery has 6 seed tracks and power ballads have 9, and both gained. Soul / easy listening has 67 and lost the most. Splitting the same gaps on the August and September static-trial means, which do not share this session’s noise, gives +0.15 below the median and +0.26 above it. I would not read this as learning helping on hard playlists.
Early in a session the learning copies mostly agree with the frozen ranking: about 8% of their picks in the first quarter sit outside its current top 25. By the last quarter that share is 42% for positive, 61% for signed, and 73% for the bandit. The grid below is the whole session, not the quarters: where each copy’s picks sat in the frozen ranking, among tracks not yet played.
Compared at the same point in the session, the bandit’s picks from outside that top 25 still beat the frozen copy by about half a point. Signed’s departures are close to a tie. Positive’s are uneven, including a loss of about 0.6 points on ranks 5-25.
Rebuilding the frozen ranking offline reproduced the tracks that copy actually played: 96% of its picks before a change on 2 November that made the next track start faster, and every pick after that change. Each copy’s first pick, before any learning, was within half a point of the frozen copy. That is one track per playlist, about what noise looks like. I later edited 61 of the 1,100 scores. Leaving those edited scores out does not move the result.
One rater: me. Twelve opportunistic same-playlist retests moved by about 4 points on average. That is too few pairs, and too messy a design, to quote a reliability coefficient. Seventy-six tracks rated on different playlists are a different question: the same recording can fit one list and not another, which is the point of playlist expansion, not rater noise.
Cells are small. Random-calibrated false-positive rates use about ten negatives per playlist, so thresholds jump in whole score points. The catalogue is 25k, not 50k. implicit_mf is graph SVD, so its failure does not indict a proper user-track model I did not run.
The twelve retests above are a within-trial question. The 487 pairs in the live section are a different comparison, across months, and that 1.43-point shift is larger than the method gaps it is meant to correct.
Supported. On this library, suggesting tracks that sound like the seed, share its tags, or sit nearby on a Last.fm similarity graph beats chance and beats global popularity. The jump that matters is onto that graph. A late-fusion hybrid and an MMR rerank sit in the same cluster as PageRank; I cannot name a winner. Playlist type still shifts which family leads. Calibrate “suggest / skip” per list. From the live sessions, the supported slice is narrower: after I rejected a track, the next suggestion from a learning copy beat the frozen one; the shorter seed lists gained while the longer ones did not; and the bandit’s picks from outside the frozen top 25 still held up.
Not supported, including some of the original hypotheses. I did not show that raw popularity is the right lever for party playlists. Tag-conditioned popularity helps; global playcount does not. I did not show that an ensemble which reweights channels per playlist beats the graph: the hybrid was trained across these eleven lists and landed 0.03 points above PageRank with overlapping intervals. I also did not show that learning during a session beats a frozen copy of the hybrid. The three learning copies average +0.20, and the interval includes zero. The bandit, which reweights channels from my scores on that playlist, was the largest of them at +0.32 and still not distinguishable from zero. I did not show that the result holds for other listeners or the full 50k library.
Default ranking, if I productize this, looks like graph or hybrid, with sonic kept for genre-homogeneous lists and tags kept instead of Last.fm playcount. I would not ship online learning as an upgrade on this evidence. I would not ship the implicit-MF rung in the form I evaluated. I would not use a universal cutoff of 6.
If you want the same experiment on your own library, the scoring interface is the easy part: 0-9 on the numpad, 30 seconds of an informative section, methods hidden. The expensive part, on 25k tracks, is admitting that a dense item-item matrix is a memory problem long before it is a modelling problem.